LLMs · RAG · Vector Search · API 2026
Kazakh Culture RAG Q&A System
A retrieval-augmented Q&A system that answers questions about Kazakh culture from real Wikipedia sources — citing them, and refusing to answer when the knowledge base doesn't cover the question.
6-stage pipeline · fetch → chunk → embed → store → retrieve → generate
- ChromaDB
- sentence-transformers
- Groq LLM API
- FastAPI
- Docker
How I built it
- Built a full RAG pipeline: fetches Wikipedia articles (nomadic pastoralism, yurts, dombra, Nauryz, cuisine, eagle hunting, the Kazakh Khanate) and splits them into overlapping ~500-word chunks.
- Embedded chunks with sentence-transformers (all-MiniLM-L6-v2) and stored them in a ChromaDB vector database for semantic retrieval.
- Generated answers with an LLM via the Groq API, grounded in retrieved context and citing sources — out-of-scope questions get “I don’t have enough information” instead of a hallucination.
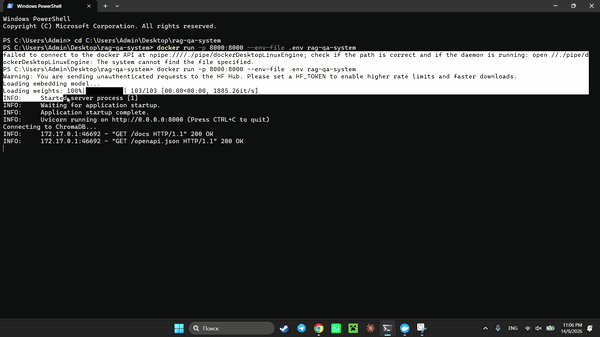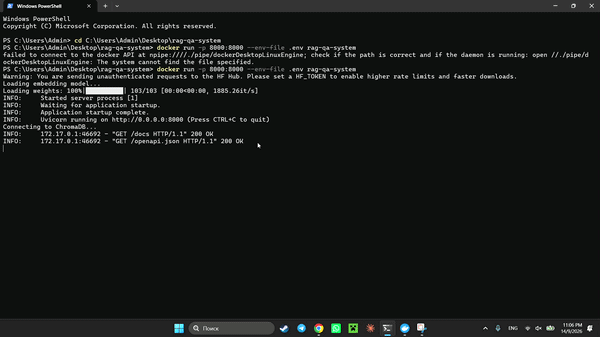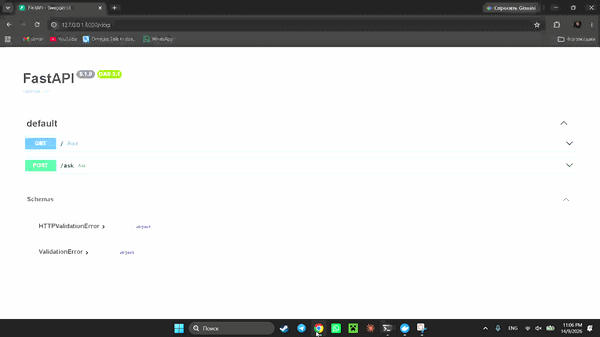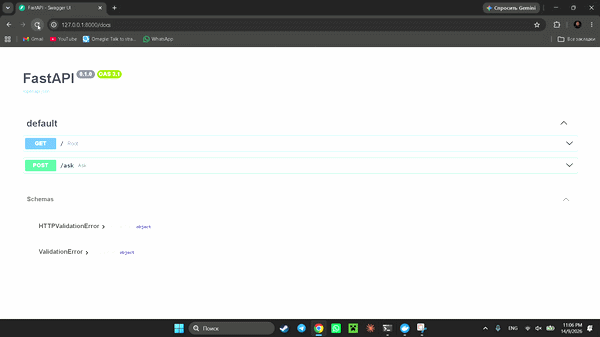
- Served through a FastAPI endpoint and containerised with Docker; the index rebuilds from scratch in under a minute.
SQL · ML Pipeline · Deployment 2026
Customer Churn Prediction System
Flags e-commerce customers who are about to churn, using 800K+ real transactions from the UCI Online Retail II dataset, served as a live risk-lookup dashboard.
40% → 67% churn recall · AUC-ROC 0.759
- SQL
- XGBoost
- SMOTE
- Pandas
- Streamlit
How I built it
- Engineered RFM (Recency, Frequency, Monetary) features with SQL CTEs, joins and aggregations over 800,000+ real e-commerce transactions (Dec 2009 – Dec 2011).
- Identified and resolved a target leakage issue in the initial feature set before it could inflate results.
- Trained an XGBoost classifier and compared a baseline against SMOTE balancing: recall on churned customers rose from 0.40 to 0.67 (+68%) while precision moved from 0.52 to 0.47 — a deliberate, measured tradeoff.
- Deployed as an interactive Streamlit dashboard for real-time customer churn-risk lookup.
NLP · Fine-tuned Transformer · REST API 2026
Sentiment Classifier
A fine-tuned DistilBERT model that classifies movie-review sentiment, served in real time through a FastAPI backend and published on Hugging Face Hub.
0.866 F1 score · 85.9% accuracy
- PyTorch
- Hugging Face Transformers
- DistilBERT
- FastAPI
How I built it
- Fine-tuned distilbert-base-uncased on IMDb (3,000 training / 1,000 test reviews) on a Colab T4 GPU, reaching 85.9% accuracy and a 0.866 F1 score.
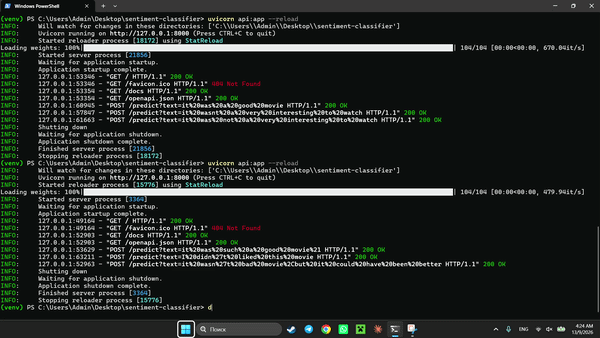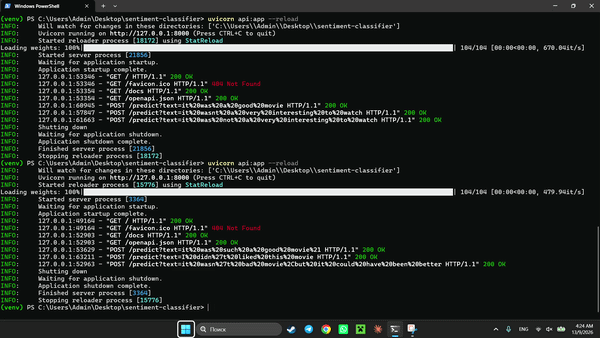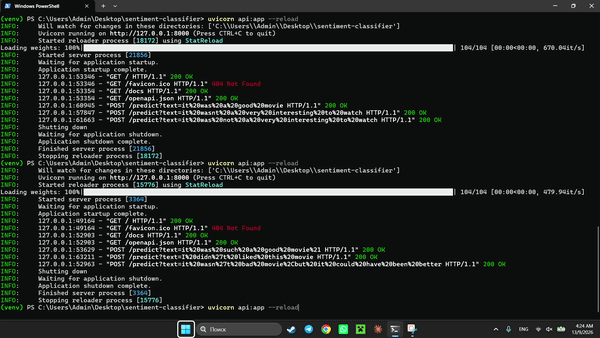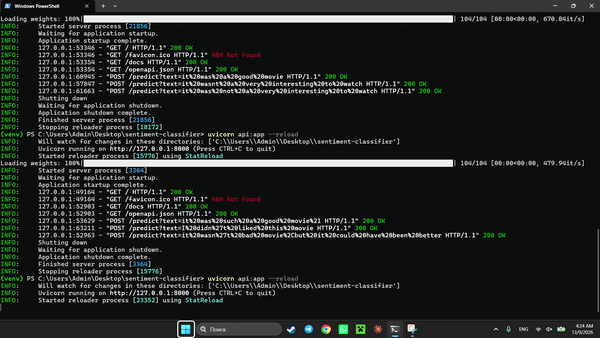
- Built a FastAPI backend serving real-time predictions, with an interactive Swagger UI for testing.
- Published the trained model to Hugging Face Hub and documented free-tier hosting constraints transparently in the README.
Regression · Feature Engineering 2025
Malaysia House Price Prediction
A full regression pipeline predicting Malaysian property prices from a 5,000+ record real-estate dataset.
0.35 → 0.60 R² score (+71%)
- LightGBM
- Scikit-learn
- Pandas
- NumPy
How I built it
- Engineered custom features — estimated total price and location clusters — and applied LightGBM gradient boosting, improving R² from 0.35 to 0.60 (a 71% relative improvement).
- Ran the full pipeline: data cleaning, outlier removal, label encoding, cross-validation and hyperparameter tuning.
LLM Agents · Tool Calling 2026
Tool-Using AI Agent
An AI agent that reasons step by step and calls real tools — live web search and timezone lookups — so its answers are grounded in actual data instead of guesses.
- smolagents
- Hugging Face Inference API
- Ollama
- Python
How I built it
- Built with Hugging Face smolagents using a Thought → Action → Observation reasoning loop.
- Gave the model real tools: a DuckDuckGo web search and a custom
get_current_time_in_timezone function, so questions like “What time is it in Tokyo right now?” are answered from live data.
- Ran models through both the Hugging Face Inference API and local Ollama, and documented why next-token prediction alone leads to hallucination.
Deep Learning · Computer Vision 2025
MNIST Digit Classifier
A convolutional neural network that recognises handwritten digits, with a visual analysis of prediction confidence.
97% test accuracy
How I built it
- Architected and trained a CNN in TensorFlow/Keras on 60,000 samples, reaching 97% test accuracy on 10,000 held-out images.
- Implemented image normalisation, dropout regularisation and a visualisation pipeline for prediction-confidence analysis.
NLP · Text Classification 2025
Spam vs Ham Classifier
A message classifier that separates spam from legitimate messages, with an interactive terminal interface for real-time predictions.
~95% accuracy on 10,000+ messages
- Scikit-learn
- Naive Bayes
- Bag-of-Words
- Pandas
How I built it
- Extracted text features with a Bag-of-Words model (CountVectorizer) and trained a Multinomial Naive Bayes classifier on 10,000+ labelled messages.
- Evaluated with accuracy, a confusion matrix and a full classification report.
- Added an interactive terminal interface for classifying new messages in real time.
↗ More on GitHub
Coursework experiments, a CIFAR-10 optimizer comparison, an NLP chatbot and more.
github.com/AlibekBerik